GNINA Docking Tutorial: CNN Scoring After AutoDock Vina
GNINA is a free molecular docking program, forked from smina and AutoDock Vina, that adds convolutional neural network (CNN) scoring. Students use it for two jobs: docking a ligand from scratch with gnina -r receptor -l ligand --autobox_ligand crystal_ligand, and rescoring poses they already made with Vina. By default it ranks poses by CNNscore, not by kcal/mol.
This guide is written by the StemSkills Lab team, who have more than 10 years of experience in structural bioinformatics, drug design and molecular modeling. It assumes you can already run a basic job from our AutoDock Vina tutorial for beginners. It is a spoke of our molecular docking learning path and sits at step 4 (docking) of the computational biology skills roadmap.
What is GNINA and how is it different from AutoDock Vina?
GNINA (pronounced “NEE-na”) is developed by the Koes lab at the University of Pittsburgh. Its family tree is short: AutoDock Vina came first, smina forked Vina to add custom scoring and easier box definition, and GNINA forked smina to add CNN models that read the protein-ligand complex as a 3D grid of atom densities.
The search engine (Monte Carlo sampling plus local optimisation) is inherited from Vina. What changes is how poses are judged. Vina scores each pose with an empirical function that returns an estimated binding energy in kcal/mol. GNINA still computes that empirical energy, but by default it then passes the final poses through an ensemble of CNNs that return two extra numbers: a pose score and a predicted affinity.
The evidence for doing this comes from the GNINA 1.0 paper (McNutt et al., Journal of Cheminformatics, 2021). With a defined binding pocket, CNN rescoring raised the Top1 success rate (top pose within 2 Å RMSD of the crystal pose) from 58% to 73% on redocking and from 27% to 37% on cross-docking, compared with Vina scoring. In the authors’ words, GNINA “outperforms AutoDock Vina scoring on redocking and cross-docking tasks.” The current major version is described in the GNINA 1.3 paper (McNutt et al., Journal of Cheminformatics, 2025), which moved the deep learning backend to PyTorch, retrained the CNNs on CrossDocked2020 v1.3, and added covalent docking.
How do I install GNINA?
The official GNINA README recommends the pre-built binary over building from source. There are three practical routes.
Route 1: the pre-built Linux binary (also works in WSL2)
At the time of writing, the latest release is v1.3.3 (June 2026), shipped as a single static file built against CUDA 12.8. It is large, about 2 GB, because the deep learning libraries are bundled inside it. Check the releases page for the current file name before you copy the command.
wget https://github.com/gnina/gnina/releases/download/v1.3.3/gnina.cuda12.8.static -O gnina
chmod +x gnina
./gnina --version
./gnina --help | less
Move the file somewhere on your PATH (for example ~/bin) so you can call gnina from any folder. On Windows, run it inside WSL2; our guide to setting up WSL2 for bioinformatics covers the Ubuntu install and Open Babel, which you will also want for file conversion.
Route 2: the official Docker image
The Koes lab publishes an image on Docker Hub as gnina/gnina. To give the container your GPU you need the NVIDIA Container Toolkit installed on the host.
docker pull gnina/gnina
docker run --gpus all -v "$PWD":/work -w /work gnina/gnina gnina --version
Route 3: Google Colab
If you have no Linux machine and no NVIDIA GPU, the README links an official example Colab notebook. Switch the runtime to a GPU and run the cells in order. Our molecular docking in Google Colab guide explains the Colab basics if you have not used it before.
Do I need a GPU?
No, but it changes how long you wait. GNINA uses the GPU for the CNN step and runs on the CPU when no usable GPU is found (you can force this with --no_gpu). With the default rescore mode the CNN only scores the final poses, so CPU runs are workable for a handful of ligands. For screening hundreds of compounds, a CUDA-capable NVIDIA card makes a large difference. Our computer requirements guide helps you decide whether your laptop is enough.
How do I run my first GNINA docking job?
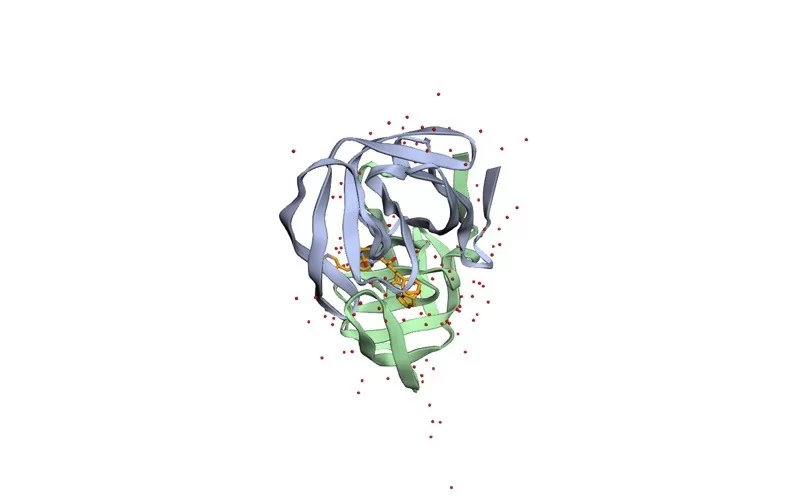
We will redock indinavir into HIV-1 protease from PDB entry 1HSG, the same system many Vina courses use, so you can compare results directly. Redocking (placing the crystal ligand back into its own pocket) is the standard first test because you know the right answer.
Step 1: get the receptor and ligand
wget https://files.rcsb.org/download/1HSG.pdb
grep "^ATOM" 1HSG.pdb > rec.pdb
grep "^HETATM" 1HSG.pdb | grep " MK1 " > mk1_xtal.pdb
wget https://files.rcsb.org/ligands/download/MK1_ideal.sdf
This gives you a protein-only receptor (waters and the ligand removed), the crystal pose of the ligand (residue code MK1) to define the search box, and an idealised 3D ligand with correct bond orders to dock. Unlike Vina, GNINA does not need PDBQT files. It reads PDB, SDF, MOL2 and PDBQT through Open Babel, and it adds hydrogens to ligands by default (--addH). For a real project, prepare the protein properly first; see how to prepare a protein and ligand for docking.
Step 2: dock
gnina -r rec.pdb -l MK1_ideal.sdf --autobox_ligand mk1_xtal.pdb \
  --seed 42 --exhaustiveness 8 --num_modes 9 \
  -o docked.sdf --log docked.log
What each option does:
-ris the rigid receptor and-lthe ligand(s) to dock.--autobox_ligandbuilds the search box around the given ligand and adds 4 Å of padding on all six sides by default (change it with--autobox_add). This replaces the sixcenter_*andsize_*numbers you type in Vina, though those options also work. Our grid box guide explains how to choose a box when no crystal ligand exists.--seedfixes the random seed so the run is reproducible. Report it in your methods.--exhaustiveness(default 8) and--num_modes(default 9) mean the same as in Vina. The trade-offs are covered in our exhaustiveness and reproducibility guide.-otakes its format from the extension. SDF keeps the scores as data fields; add.gzto compress large screens.
When there is no known ligand and you want to search the whole protein, the README example is --autobox_ligand rec.pdb --exhaustiveness 64. Expect lower accuracy: in the GNINA 1.0 paper, whole-protein Top1 on redocking was 38% with CNN rescoring against 31% for Vina scoring. Our blind docking guide explains why pocket-defined docking is preferred whenever you can find the site.
Want the guided, hands-on version?
Our live Molecular Modeling & MD Simulations cohort bootcamp takes you from zero to running real docking and MD workflows, with a portfolio project for your grad-school applications.
How do I read GNINA output: affinity, CNNscore or CNNaffinity?
For each pose GNINA prints a row in the terminal and writes the same values as SDF data fields (minimizedAffinity, CNNscore, CNNaffinity). They answer different questions, and mixing them up is the most common beginner mistake.
| Value | What it estimates | Units and direction | Use it for |
|---|---|---|---|
| Affinity (minimizedAffinity) | Binding energy from the empirical Vina-type function | kcal/mol, more negative is better | Comparing with Vina results and older literature |
| CNNscore | Probability that the pose is close to the true binding mode | 0 to 1, higher is better | Choosing which pose of a ligand to believe |
| CNNaffinity | Predicted binding affinity of the pose | pK units (like pKd), higher is better | A second, independent opinion when ranking different ligands |
Two rules follow from this table. First, rank the poses of one ligand by CNNscore; this is GNINA’s default sort order (change it with --pose_sort_order). Second, never rank different ligands by CNNscore alone. A CNNscore of 0.9 says “this is probably the right pose”, not “this compound binds tightly”. For compound ranking, look at CNNaffinity and the Vina affinity together, and treat both as hypotheses to test. Our guide to interpreting molecular docking results explains what any docking score can and cannot tell you.
To check the redock, open docked.sdf and mk1_xtal.pdb together in PyMOL and compare the top pose with the crystal pose. A top pose within about 2 Å RMSD of the crystal pose counts as a success, which is the same cut-off the GNINA papers use. Our PyMOL commands for docking page lists the alignment and RMSD commands.
How do I rescore my existing AutoDock Vina poses with GNINA?
This is the cheapest way to add GNINA to a project you have already finished in Vina. You keep your Vina poses and ask the CNN for a second opinion. Convert the Vina output to SDF first so each pose becomes a separate record:
obabel vina_out.pdbqt -O vina_poses.sdf
gnina -r rec.pdb -l vina_poses.sdf --score_only
gnina -r rec.pdb -l vina_poses.sdf --minimize -o vina_min.sdf--score_onlyscores each pose exactly where it sits. It prints the empirical affinity plus CNNscore and CNNaffinity for every pose.--minimizefirst relaxes each pose locally, then scores it, and writes the minimised poses to the output file. Use it when poses come from another program and may have small clashes under GNINA’s atom typing.
Use the same receptor structure that you docked against in Vina (a PDB version of it is fine), or the scores will not be comparable. A useful pattern in a thesis is a short table listing, for each compound, the Vina top-pose affinity, its CNNscore and its CNNaffinity, and a note on whether the scoring methods agree.
Which –cnn_scoring mode should I use?
The --cnn_scoring option controls when the CNN is used during docking. The descriptions and speed notes below come from the official README.
| Mode | What the CNN does | Cost | When to use |
|---|---|---|---|
none | Not used; empirical scoring only | Fastest | Pure Vina or Vinardo docking (--scoring vinardo) inside GNINA |
rescore (default) | Reranks the final poses | Cheapest CNN option | Almost every student project |
refinement | Refines poses after the Monte Carlo chains, then ranks them | About 10 times slower than rescore on a GPU | A few important ligands where pose quality matters most |
all | Scores every step of the search | About 1000 times slower than rescore | Not recommended by the developers |
The default CNN in version 1.3 is an ensemble of three models (dense_1_3, dense_1_3_PT_KD_3 and crossdock_default2018_KD_4). The GNINA 1.0 ensemble is still available with --cnn default1.0 if you need to reproduce an older paper. Stay with the default unless you have a specific reason, and state the version and model in your methods.
When is GNINA worth it instead of plain Vina?
GNINA is worth the extra install when pose accuracy matters (you plan to run MD on the top pose, or you are explaining a binding mode in a thesis) and when you want an independent check on Vina’s ranking. Plain Vina is still the better choice when you must match a published protocol exactly or when your supervisor’s pipeline is built on the Vina Python bindings.
| Feature | AutoDock Vina 1.2 | smina | GNINA 1.3 |
|---|---|---|---|
| Scoring | Vina, Vinardo, AutoDock4 | Vina by default, custom empirical functions | Empirical (Vina default) plus CNN ensemble |
| Input formats | PDBQT | Any format Open Babel reads | Any format Open Babel reads |
| Box definition | center and size | center and size, or --autobox_ligand | center and size, or --autobox_ligand |
| GPU | Not used | Not used | Used for CNN scoring, optional |
| Speed | Fast | Fast | Slower; depends on CNN mode and GPU |
| Covalent docking option | Not built in | Not built in | Built in (--covalent_rec_atom) |
| Cite in methods | Eberhardt et al., JCIM 2021 | Koes et al., JCIM 2013 | McNutt et al., J Cheminform 2025 (and 2021) |
For Vina, cite the AutoDock Vina 1.2.0 paper (Eberhardt et al., Journal of Chemical Information and Modeling, 2021). A methods sentence for GNINA can read: “Docking was performed with GNINA v1.3.3 (McNutt et al., 2025) using the default CNN ensemble in rescore mode, exhaustiveness 8, a box defined by the crystal ligand with 4 Å padding, and random seed 42.” Our guide to writing the methods section of a docking study lists everything else a reviewer will ask for. For the older Vina versus AutoDock4 choice, see AutoDock Vina vs AutoDock4, and for covalent ligands see our covalent docking tutorial.
What are the common GNINA errors and how do I fix them?
1. GNINA does not find the GPU and runs on the CPU
Fix: run nvidia-smi. If it fails, the NVIDIA driver is missing (in WSL2 the driver is installed on Windows, not inside Ubuntu). In Docker, add --gpus all and install the NVIDIA Container Toolkit. If you have several GPUs, pick one with --device. Runs still complete on the CPU, only slower.
2. A run is far slower than expected
Fix: check that you did not set --cnn_scoring refinement or all by copying someone else’s command. Return to the default rescore, keep exhaustiveness at 8 while testing, and limit threads with --cpu if you share the machine. Whole-protein boxes also cost far more time than pocket boxes.
3. Poses land outside the pocket
Fix: the autobox ligand file is probably wrong. Make sure it holds only the bound ligand, not the whole PDB, and that it shares the receptor’s coordinate frame (a ligand from a different PDB entry must be superposed first). If the ligand is large, increase padding with --autobox_add 8. Our guide to finding the binding site helps when no co-crystal ligand exists.
4. Input format confusion: PDBQT, PDB and SDF
Fix: GNINA reads all three, but PDB and PDBQT ligand files carry no reliable bond orders, which can mislabel aromatic rings or charged groups. Dock ligands from SDF or MOL2 with correct bond orders (for example the RCSB “ideal” SDF or a file prepared in Open Babel). Keep PDBQT for rescoring Vina output, as shown above.
5. CNNscore is high but the affinity looks poor
Fix: this is not an error. CNNscore judges the pose, not binding strength. A weak binder can still have a confidently predicted pose. Rank compounds using CNNaffinity and the empirical affinity together, then check the top candidates with an ensemble or MD-based follow-up before making claims.
6. Results change between runs
Fix: docking is stochastic. Set --seed and record it. If the top pose still differs between seeds, raise exhaustiveness; disagreement across seeds is itself a sign that the pose is uncertain.
Many of these problems overlap with Vina’s; our list of AutoDock Vina errors and fixes covers the shared ones. When you move from one ligand to a library, the loop structure in our batch docking guide carries over almost unchanged, and GNINA also accepts a multi-ligand SDF with -l.
Frequently asked questions
Is GNINA free for academic use?
Yes. GNINA is open source and dual licensed under GPL and Apache, according to its GitHub repository. You can use it for coursework, theses and publications at no cost.
Can I use GNINA on Windows?
Not natively. Run the Linux binary inside WSL2, use the Docker image, or use the official Colab notebook. The README confirms that the pre-built binary can be used in WSL.
Is a higher CNNscore the same as a stronger binder?
No. CNNscore estimates how likely the pose is to be correct, on a 0 to 1 scale. Binding strength is estimated by CNNaffinity (pK units, higher is stronger) and by the empirical affinity in kcal/mol (more negative is stronger).
Can GNINA rescore poses from AutoDock Vina?
Yes. Convert the Vina PDBQT output to SDF with Open Babel, then run GNINA with --score_only to score the poses as they are, or with --minimize to relax and score them.
Which GNINA paper should I cite?
The README lists GNINA 1.3 (McNutt et al., Journal of Cheminformatics, 2025) as the primary application citation and GNINA 1.0 (2021) for the previous version. Cite the paper that matches the version you ran, and give the exact version number from gnina --version.
Does GNINA replace molecular dynamics?
No. Better pose scoring still gives a single static snapshot. Use MD to test whether a docked pose is stable over time; our comparison of molecular docking vs molecular dynamics explains how the two fit together.
Want the guided, hands-on version?
Our live Molecular Modeling & MD Simulations cohort bootcamp takes you from zero to running real docking and MD workflows, with a portfolio project for your grad-school applications.